Gemini 4 Neon vs GPT-6.2 (Astra & Sol) vs Claude Fable 5.2: November 2026 AI Guide
Compare Google Gemini 4 Neon, OpenAI GPT-6.2 Astra & Sol, and Anthropic Claude Fable 5.2: coding benchmarks, 1M context, API pricing, fast modes, and setup.
Table of Contents
- 1. The November 2026 Frontier Showdown at a Glance
- 2. Interactive Model Selector for Your Workflow
- 3. Specs & API Pricing Compared Side by Side
- 4. Coding, Agentic & Reasoning Benchmarks
- 5. Thinking Levels, Fast Modes & Ready-to-Run API Calls
- 6. Migration Pitfalls & Scenario Matcher
- 7. Practical 4-Step Multi-Model Routing Strategy
- 8. Frequently Asked Questions (FAQ)
1. The November 2026 Frontier Showdown at a Glance
November 2026 cemented a new baseline for production AI: 1M-token context windows, tunable reasoning depth, dedicated fast inference tiers, and agent-first coding harnesses are now standard across all three labs. Yet each release stakes out a distinct role:
- Anthropic Claude Fable 5.2 (
claude-fable-5-2): Anthropic's generally available flagship for hard software engineering, finance, science, and long-horizon agents. Compared to Fable 5.1, it drops pricing by 20% ($8/$40), accelerates output speed by up to 30%, introduces a 2.5x Fast Mode, and makes Adaptive Thinking always-on. - OpenAI GPT-6.2 Astra & Sol (
gpt-6.2-astra,gpt-6.2-sol): A coordinated pair—Astra ($8/$40) for repository-scale engineering, cybersecurity, scientific research, and complex computer use, alongside Sol ($2/$10) for fast, cost-effective daily coding and code reviews. Both support OpenAI's new Ultrafast tier, and Astra is OpenAI's first externally deployed model to reach the "High" threshold for AI Self-Improvement under its Preparedness Framework. - Google Gemini 4 Neon (
gemini-4-neon): Slotted cleanly between Gemini 4 Hydrogen ($1.50/$7.50) and Gemini 4 Carbon ($4/$20standard;$2/$10promo through Nov 30). At$3/$15, Neon brings near-Carbon reasoning with faster turnarounds, a unified 1M-token context window (with long-decode background output up to 1M tokens), and native multimodal support across text, image, audio, video, PDF, and Office documents.
2. Interactive Model Selector for Your Workflow
Not sure which model belongs in your IDE, CLI, or backend pipeline? Pick your top priority below to see the recommended fit.
Google Gemini 4 NeonHigh-value frontier reasoning, 1M recall & multimodal
“Near-Carbon intelligence at mid-tier pricing”
- Release / Model ID
- Nov 18, 2026 / gemini-4-neon
- Standard API (per 1M)
- $3.00 in / $15.00 out ($0.15 cached)
- Context / Output
- 1M unified / 64K sync (1M background decode)
- Standout Strengths
- GraphWalks 95.2%, AA Coding Agent #1, native video/audio/PDF
OpenAI GPT-6.2 (Astra & Sol)Everyday Sol + frontier science, security & Ultrafast Astra
“Two-tier efficiency plus sub-second agent loops”
- Release / Model IDs
- Nov 17, 2026 / gpt-6.2-astra, gpt-6.2-sol
- Standard API (per 1M)
- Sol $2/$10 · Astra $8/$40 (surcharge >272K in)
- Context / Output
- 1.05M (922K max input) / 128K output
- Standout Strengths
- Agents' Last Exam 78.3%, GPQA 97%, Ultrafast mode
Anthropic Claude Fable 5.2Top-tier software engineering & flat 1M-context billing
“93% SWE-bench Pro with 2.5x Fast Mode”
- Release / Model ID
- Nov 9, 2026 / claude-fable-5-2
- Standard API (per 1M)
- $8.00 in / $40.00 out ($0.20 cache read)
- Context / Output
- 1M (flat pricing across full 1M) / 128K output
- Standout Strengths
- SWE-bench Pro 93.0%, Multilingual 96.6%, 2.5x Fast Mode
3. Specs & API Pricing Compared Side by Side
Pricing converged neatly at the very top—both GPT-6.2 Astra and Claude Fable 5.2 list at $8.00 input / $40.00 output per million tokens—while the real budget battle happens in the $2–$4 input middle tier.
Flagship & Mid-Tier Lineup (USD per 1M Tokens)
| Model | Release Date | API Model ID | Context / Max Output | Standard In / Out | Cached Read | Fast / Priority Tier | Notes |
|---|---|---|---|---|---|---|---|
| Gemini 4 Neon | Nov 18, 2026 | gemini-4-neon | 1M unified / 64K (1M async) | $3.00 / $15.00 | $0.15 (95% off) | Priority ($5.40/$27) | Paid tier only; Batch 50% off |
| Gemini 4 Carbon | Nov 10, 2026 (GA) | gemini-4-carbon | 1M / 64K+ | $4.00 / $20.00* | — | — | *$2/$10 intro promo through Nov 30 |
| Gemini 4 Hydrogen | Nov 12, 2026 | gemini-4-hydrogen | 1M / 64K | $1.50 / $7.50 | — | — | Free & paid tiers available |
| GPT-6.2 Astra | Nov 17, 2026 | gpt-6.2-astra | 1.05M / 128K | $8.00 / $40.00 | $0.40 | Fast 2x / Ultrafast 3x* | >272K input: 2x in, 1.5x out |
| GPT-6.2 Sol | Nov 17, 2026 | gpt-6.2-sol | 1.05M / 128K | $2.00 / $10.00 | $0.10 | Fast 2x / Ultrafast 3x* | Exactly 1/4 of Astra's rates |
| Claude Fable 5.2 | Nov 9, 2026 | claude-fable-5-2 | 1M / 128K | $8.00 / $40.00 | $0.20 (0.025x) | Fast 2x ($16/$80) | No long-context surcharge |
| Claude Opus 5.5 | Sep 22, 2026 | claude-opus-5-5 | 1M / 128K | $4.00 / $20.00 | $0.20 | Available | Recommended general flagship |
4. Coding, Agentic & Reasoning Benchmarks
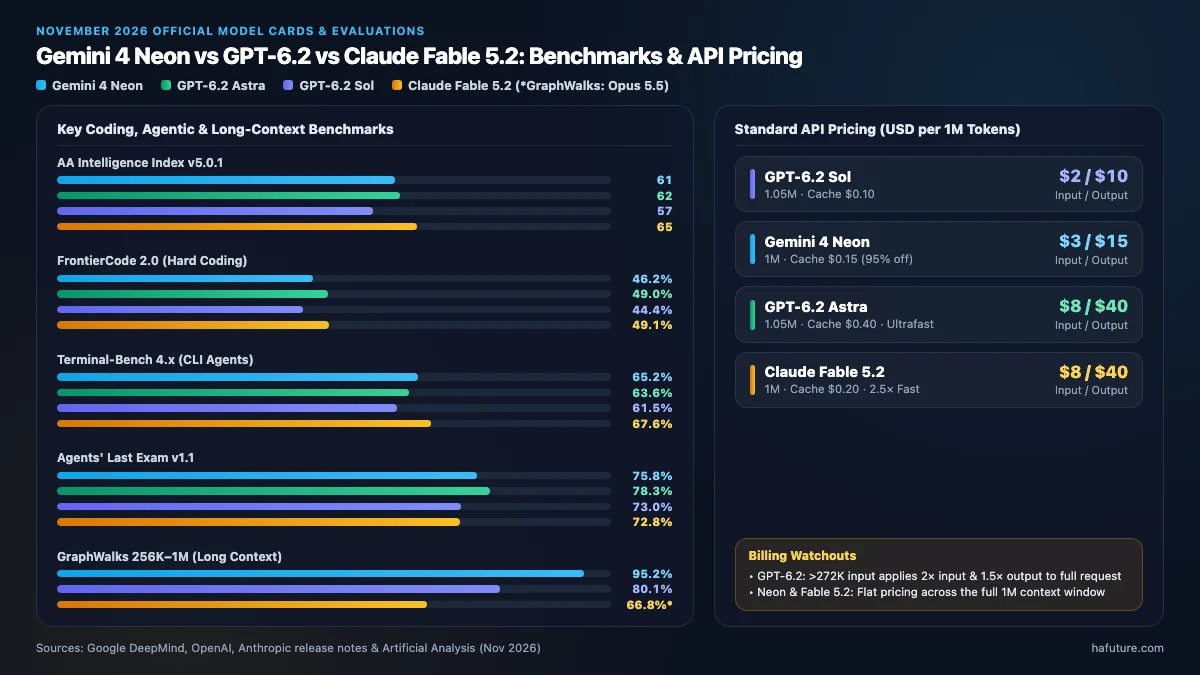
With legacy SWE-bench Verified largely saturated, November 2026 evaluations center on harder, repo-scale and multi-step benchmarks—SWE-bench Pro, FrontierCode 2.0, Terminal-Bench 4.x, SWE-sweep, and Agents' Last Exam.
Verified Benchmark Snapshot
| Category | Benchmark | Gemini 4 Neon | GPT-6.2 Astra | GPT-6.2 Sol | Claude Fable 5.2 | Key Takeaway |
|---|---|---|---|---|---|---|
| Overall Intelligence | AA Intelligence Index v5.0.1 | 61 (xhigh) / 60 (high) | 62 (max/xhigh) | 57 (max) | 65 (max) / 62 (high) | Fable 5.2 max leads; Neon hits 60–61 at $3/$15 |
| Hard Coding | FrontierCode 2.0 | 46.2% (high) | 44.2% (OpenAI) / 49.0% (AA) | 43.8% (OpenAI) / 44.4% (AA) | 49.1% (xhigh) / 45.3% (high) | Sol stays within 0.5 pts of Astra at ~1/5 task cost |
| SWE Repo Fixes | SWE-bench Pro / Multilingual | — (SWE-sweep 39.0%) | — (SecureSWE 65.7%) | — (SecureSWE 55.6%) | 93.0% / 96.6% | Fable 5.2 sets the pace for multi-language patching |
| Terminal Agents | Terminal-Bench 4.0 / 4.1 | 65.2% (4.1) | 63.6% (Codex) | 61.5% (4.1) | 67.6% (4.0) | Tight competition in real shell workflows |
| Science & Research | Terminal-Bench-Science 0.1 | 70.5% | 77.1% | 68.0% | — | Astra also hits 97.0% on GPQA Diamond |
| Agentic Knowledge | Agents' Last Exam v1.1 | 75.8% | 78.3% (xhigh) | 73.0% | ~72.8% | Astra leads at $2.89/task (+5.5 pts over Fable 5.2) |
| Long Context | GraphWalks (256K–1M, BFS F1) | 95.2% | — | 80.1% | — (Opus 5.5: 66.8%) | Clear long-context recall advantage for Gemini 4 |
| Enterprise Automation | AutomationBench | 56.3% | — | 41.3% | 51.4% (max) | Strongest multi-app workflow execution on Neon |
What the Numbers Actually Mean in Practice
- The harness multiplies model intelligence: On SWE-sweep, Gemini 4 Neon scored 12.8% inside the minimal
mini-SWEharness, then leaped 3x to 39.0% inside Google's Antigravity harness with subagent orchestration. Pairing a strong model with a capable harness matters as much as the weights. - GPT-6.2 Sol is the sleeper value winner: Coming within 0.4–0.5 points of Astra on FrontierCode 2.0 at one-quarter the token price makes Sol an ideal default for Codex CLI, PR reviews, and CI automation, reserving Astra for security hardening (PatchBench 79.7%) and deep scientific reasoning.
- Watch the
maxeffort token cliff on Fable 5.2: Pushing Claude Fable 5.2 fromhightomaxadds 3 points on Artificial Analysis (62 → 65) but consumes roughly 3.2x more output tokens. Keep daily runs onmediumorhigh, and savexhigh/maxfor genuinely thorny refactors.
5. Thinking Levels, Fast Modes & Ready-to-Run API Calls
All three APIs now expose explicit knobs for reasoning depth and inference speed. Use these verified request templates to test each model immediately:
curl -X POST "https://generativelanguage.googleapis.com/v1beta/interactions" \
-H "x-goog-api-key: $GEMINI_API_KEY" \
-H "Content-Type: application/json" \
-d '{
  "model": "gemini-4-neon",
  "input": "Diagnose the memory leak in this Next.js route handler and output a minimal patch.",
  "generation_config": {
    "thinking_level": "high"
  }
}'6. Migration Pitfalls & Scenario Matcher
Swapping only the model string in existing code can trigger immediate 400 errors on this generation—especially around deprecated thinking budgets, sampling parameters, and long-context pricing thresholds. Search your scenario below:
- Running dozens of PR reviews, unit tests, and feature tasks every dayDaily Driver· Coding & Agents
Avoid burning $8/$40 tokens on routine turns. Sol is now the default model in Codex v0.171, while Neon shines when prompts pull in large multi-file context.
Recommended Move:GPT-6.2 Sol ($2/$10) or Gemini 4 Neon ($3/$15)Alternative:Claude Opus 5.5 ($4/$20) - Cross-cutting multi-file refactors or deeply tangled production bugsPeak Accuracy· Coding & Agents
With 93.0% on SWE-bench Pro and 96.6% on SWE-bench Multilingual, Fable 5.2 is the safest bet for complex codebases. Start at high or xhigh before touching max.
Recommended Move:Claude Fable 5.2 (effort: xhigh)Alternative:GPT-6.2 Astra - Analyzing 300K–800K token monorepos, long screen recordings, or dense PDFsLong Context· Coding & Agents
Neon posts 95.2% on GraphWalks (256K–1M) and 89.0% on LVBench long-video comprehension with flat pricing across the full 1M context window.
Recommended Move:Gemini 4 Neon (thinking_level: high)Alternative:Claude Fable 5.2 (text/image/PDF) - My GPT-6.2 API bill suddenly doubled on long agent sessionsBilling Alert· Cost & Latency
Crossing 272K input tokens on GPT-6.2 Astra or Sol applies 2x input/cache and 1.5x output rates to the entire request.
Recommended Move:Compact sessions before hitting 272K input tokensAlternative:Route >272K sessions to Gemini 4 Neon or Fable 5.2 - Interactive workflows where output speed directly affects UXLow Latency· Cost & Latency
Sol Ultrafast is $6/$30 through Feb 2027 (and included in ChatGPT Pro $200). Fable 5.2 Fast accelerates output generation up to 2.5x across the full 1M context.
Recommended Move:GPT-6.2 Sol Ultrafast or Claude Fable 5.2 FastAlternative:Gemini 4 Hydrogen ($1.50/$7.50) - Upgrading to claude-fable-5-2 throws 400 Bad Request errorsBreaking Change· API Breaking Changes
Fable 5.2 enforces always-on Adaptive Thinking and Strict Prefix Checks—modifying system prompts or earlier messages before replaying a thinking block returns 400.
Recommended Move:Remove temperature, top_p, thinking.disabled, and forced tool_choiceAlternative:Use output_config.effort and tool_choice: auto - Gemini 4 Neon rejects my existing thinking configuration with HTTP 400Breaking Change· API Breaking Changes
Neon rejects the legacy minimal level and errors whenever deprecated thinkingBudget is sent alongside thinkingLevel.
Recommended Move:Set thinking_level to low, medium, high, or xhighAlternative:Delete deprecated thinkingBudget fields
7. Practical 4-Step Multi-Model Routing Strategy
Rather than locking into a single vendor, top engineering teams in late 2026 route tasks across two or three complementary models:
- 1Standardize 70–80% of daily traffic on a mid-tier model
gpt-6.2-sol / gemini-4-neonAssign routine coding, PR summaries, tests, and documentation to GPT-6.2 Sol ($2/$10) or Gemini 4 Neon ($3/$15, medium/high) to keep monthly spend predictable.
- 2Escalate the hardest 15–20% to a frontier flagship
claude-fable-5-2 / gpt-6.2-astraSend deep multi-file refactors to Claude Fable 5.2 (high/xhigh) and reserve GPT-6.2 Astra for security patches, scientific reasoning, and strict legal/data tasks.
- 3Stack prompt caching and Batch APIs to cut costs 50–95%
Batch (0.5x) + Prompt CacheAll three labs offer 50% Batch discounts. Take advantage of Neon's 95% cache read discount ($0.15) and Fable 5.2's $0.20 (0.025x) cache reads for repeated repo context.
- 4Unify subscriptions and APIs in a multi-agent workspace
Paseo / OpenCode / Claude Code / CodexUse a workspace orchestrator or model-agnostic CLI so you can switch seamlessly between Claude Code, Codex, and Antigravity without rebuilding your workflow.
8. Frequently Asked Questions (FAQ)
Q1. Why use Gemini 4 Neon ($3/$15) while Gemini 4 Carbon is on a $2/$10 promo?
Q2. What is the difference between Claude Fable 5.2 and Claude Mythos 5.2?
Q3. Where are GPT-6.2 Astra and Sol available right now?
Q4. How do safeguard refusals work on Claude Fable 5.2?
Q5. Are these models already supported in popular coding CLIs?
Convert Monthly AI API Costs with Hafuture Exchange Rate Calculator
Estimate your USD API bills for Gemini 4 Neon, GPT-6.2, and Claude Fable 5.2 in your local currency with real-time exchange rates—100% private in your browser.